
Workload placement
Decide which jobs need reserved GPUs, which can share a pool, and which can wait for available capacity.
AIMPLE Runtime
Give each workload
the right compute.
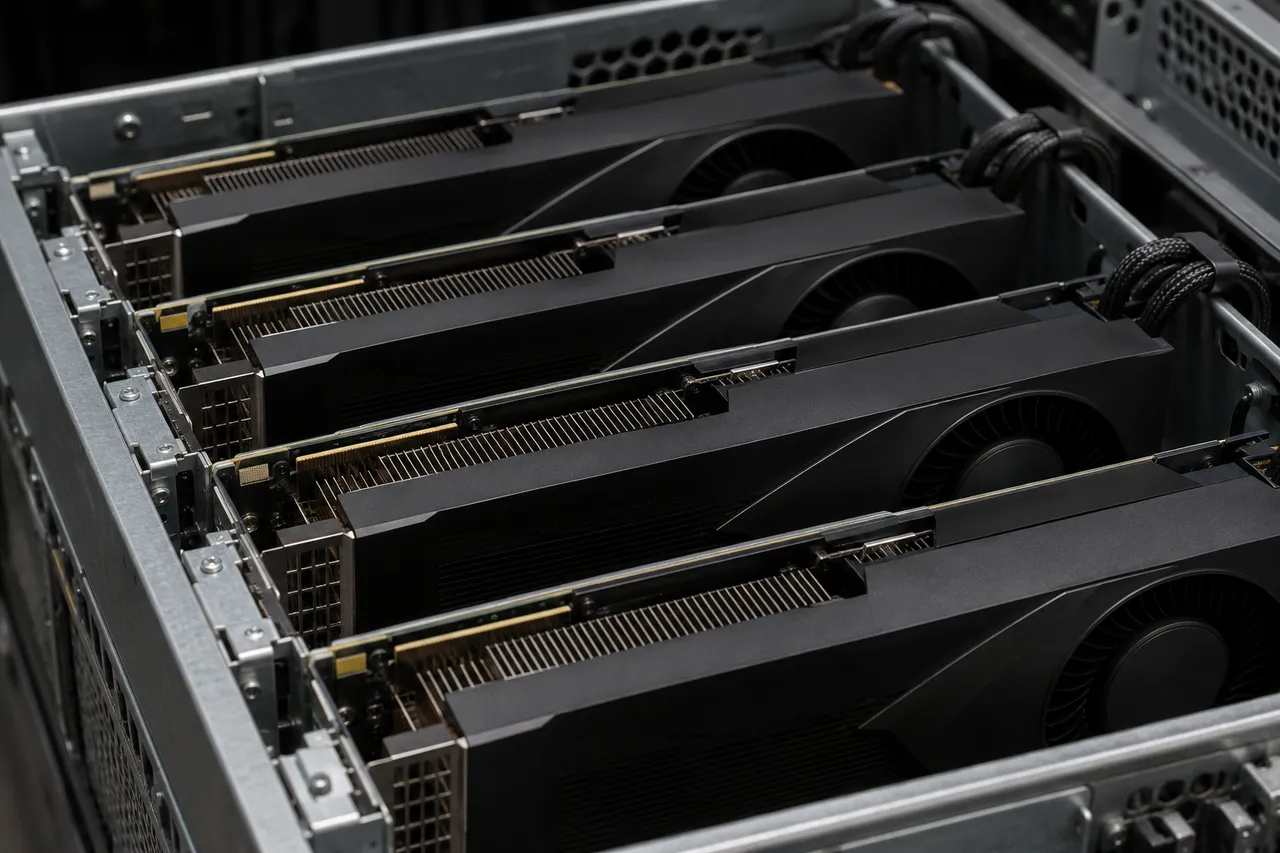
Inference, media generation, training, and streaming place different demands on compute. Plan execution around latency, memory, available capacity, and proximity to devices.
| Workload | Constraint | Placement decision |
|---|---|---|
| Interactive inferenceInference | Latency-sensitive | Reserve capacity |
| Media renderingGeneration | Throughput | Assign to a GPU pool |
| Model fine-tuningTraining | Flexible start time | Queue for capacity |
| Live video processingStreaming | Real-time delivery | Process near the venue |
Inputs for placement decisions
Service targets
Record peak concurrency and acceptable response or completion time for each workload.
GPU requirements
Check model memory, supported accelerator types, and resource needs under representative load.
Scheduling policy
Group workloads by priority and define how each group handles bursts, queue time, and capacity shortages.